

Video DeltaNet: Hybrid Attention to Speed Up Video Models with Near-Lossless Quality
[Blog] [Code] [🤗 Weights] [ModelScope] [License]
We release VDN-Minimax-H3 (VDN-H3), a hybrid-attention model that generates video faster than it plays, powered by MiniMax H3. It offers these key features:
- Fast inference: With SGLang Diffusion on 8×B200 GPUs, VDN-H3 generates a 14.4-second clip in about 9.0 seconds end-to-end, including 6.9 seconds for denoising, using 8 denoising steps.
- Hybrid Architecture: We propose a hybrid-attention architecture: one frame-wise linear attention branch that is highly efficient, and a softmax branch that maintains the backbone's visual quality and consistency.
- Plug-and-Play: The checkpoint adds a separate linear attention branch and two small LoRA adapters that can be merged into the backbone during inference without touching the backbone weights.
- Fully open-source: We don't just open-source the weights. The optimized inference stack and its corresponding training code are released together.
This repository holds the weights. Read the Blog for the architecture, training method, benchmarks, and qualitative results. The inference and training code, together with the setup instructions, is available at OpenVDN/vdn-minimax-h3.
News
- September 14, 2026: SGLang Diffusion now supports VDN-H3, achieving its fastest reported performance: 6.9 seconds for denoising and about 9.0 seconds end-to-end for a 14.4-second video on 8×B200 GPUs. See the MiniMax-H3 cookbook for more details.
- September 8, 2026: We support I2VA, FL2VA and L2VA now with the same checkpoint.
- September 6, 2026: We released the VDN-H3 blog, training and inference code, and model weights.
Set up the environment
Before you begin, please read the license before downloading or running VDN-H3.
- Clone the VDN-H3 repository from GitHub.
git clone https://github.com/OpenVDN/vdn-minimax-h3.git
cd vdn-minimax-h3
- Create the environment. We recommend PyTorch 2.13 (
torch.__version__=2.13.0+cu129) and installing FlashAttention 4: on Hopper and data-center Blackwell the window softmax runs on its kernels, through FlexAttention's Flash backend or directly. On Ampere, Ada and consumer Blackwell (RTX 50 series), or without it, the window softmax runs on FlexAttention's Triton kernel and on PyTorch's own varlen attention.
conda create -n vdn python=3.12 -y
conda activate vdn
pip install uv

uv pip install torch==2.13.0 --index-url https://download.pytorch.org/whl/cu129
- Install the other packages shown in
pyproject.toml,flash-attn-4included (--prerelease=allowis needed for its pre-releasenvidia-cutlass-dsldependency); on Ampere, Ada and consumer Blackwell neither it nor the regularflash-attnis used, as attention there runs on PyTorch's own kernels.
uv pip install --prerelease=allow -e .
- Install the patched Diffusers. The setup script handles everything:
bash scripts/setup_diffusers.sh
Inference with Diffusers
The quickest way to a first render is using diffusers, as we already release the checkpoints as modular diffusers components:
import torch
from accelerate import cpu_offload_with_hook
from diffusers import ModularPipeline
from diffusers.hooks import apply_group_offloading

pipe = ModularPipeline.from_pretrained("OpenVDN/vdn-minimax-h3", workflow="t2va")
pipe.load_components(trust_remote_code=True, torch_dtype=torch.bfloat16)

apply_group_offloading(pipe.text_encoder, onload_device="cuda", offload_type="leaf_level",
                       use_stream=True)
_, vae = cpu_offload_with_hook(pipe.vae, execution_device="cuda")
cpu_offload_with_hook(pipe.audio_vae, execution_device="cuda", prev_module_hook=vae)
pipe.transformer.to("cuda")

out = pipe(prompt="a prompt", num_frames=345, num_inference_steps=9,
           output=["videos", "audio", "sampling_rate"])
num_inference_steps counts sigma grid points, so 9 of them is 8 model evaluations. infer_diffusers.py runs the same as a script, keyframes included.
On a 24 GB card, stream the transformer in one block at a time: swap pipe.transformer.to("cuda") for the line below, or add --offload_dit to the script. 345 frames then peak at 22 GB, 20 in fp8.
apply_group_offloading(pipe.transformer, onload_device="cuda", offload_type="block_level",
                       num_blocks_per_group=1, use_stream=True)
The transformer can be offloaded per model or per block, but not per leaf. Its window softmax runs on FlexAttention; softmax_backend={"transformer": "decomposed"} in load_components selects the decomposition the code repository's own scripts use instead, FA4's varlen kernel on Hopper and data-center Blackwell and PyTorch's on Ampere, Ada and consumer Blackwell.
fp8 is torchao's (pip install torchao): fp8={"transformer": True} in load_components, or --fp8 for the script, puts every wide Linear in fp8 e4m3, and a quantization_config of your own, a TorchAoConfig, is applied in its place after the LoRA merge.
Inference with SGLang
SGLang Diffusion provides native VDN-H3 serving for T2VA and FL2VA. Install SGLang and launch the 8×B200 configuration below. Set --num-gpus to 1, 2, or 4 for the corresponding smaller configuration:
uv pip install "sglang[diffusion]" --prerelease=allow

sglang serve \
  --model-path OpenVDN/vdn-minimax-h3 \
  --num-gpus 8 \
  --quantization fp8 \
  --attention-backend hybrid_window_attn_h3 \
  --performance-mode speed \
  --warmup-num-frames 345 \
  --warmup-resolutions 1344x768 \
  --port 30010
With MXFP8, denoising takes 47.6, 25.9, 13.1, and 6.9 seconds on 1, 2, 4, and 8 B200 GPUs, respectively. The 8-GPU configuration returns the finished 14.4-second video in about 9.0 seconds end-to-end after warm-up. See the MiniMax-H3 cookbook for more details.
Inference with our repository
Download the weights
To render through the optimized stack instead -- fp8, the tuned kernels, and Ulysses across eight GPUs, which is where the numbers under Results come from -- start from the code repository and download everything (about 82 GB) into ckpts/ using
hf download OpenVDN/vdn-minimax-h3 --local-dir ckpts
or from ModelScope with
modelscope download --model OpenVDN/vdn-minimax-h3 --local_dir ckpts
The layout will look like
ckpts/
  h3-base/             the released MiniMax-H3: transformer, video and audio VAEs, schedulers · 72 GB
  stage-b-step-2000/   VDN-H3-50-step: linear_branch/ + adapters/default/ LoRA · 4.3 GB
  stage-dmd-step-250/  VDN-H3-8-step: the above + adapters/turbo/ · 5.1 GB
stage-dmd-step-250 is the 8-step model the headline numbers use; stage-b-step-2000 is the 50-step model it is distilled from. Each directory describes itself: model_spec.json records the hybrid architecture, metadata.json the training recipe, and the learned tensors sit in linear_branch/model.safetensors and adapters/<name>/adapter_model.safetensors.
Render a video
First clone and set up the code repository. Then, from the root of that repository, run the model on a single GPU:
bash scripts/inference/8nfe_tuned_fp8.sh
Note that the first run needs to compile all of the kernels, which might take several minutes. Later runs can reuse the cache.
Use your own prompt
For your own prompt, you should first encode it using the Qwen3-VL-32B VLM, then render it through the main diffusion model:
python src/inference/encode_prompt.py --prompt "..." --out prompts/mine.pt

python src/inference/infer.py \
  --config configs/inference/8nfe_tuned_fp8.yaml \
  checkpoint=ckpts/stage-dmd-step-250 \
  render.prompt_file=prompts/mine.pt \
  render.out=results/mine.mp4
We strongly recommend rewriting it first using H3-Context-IR or the official prompt-writing skills before encoding it. This can greatly improve the generated video quality.
Supporting FL2VA, I2VA, and L2VA
The same checkpoints also generate from keyframes. We provide an FL2VA example in prompts/image/:
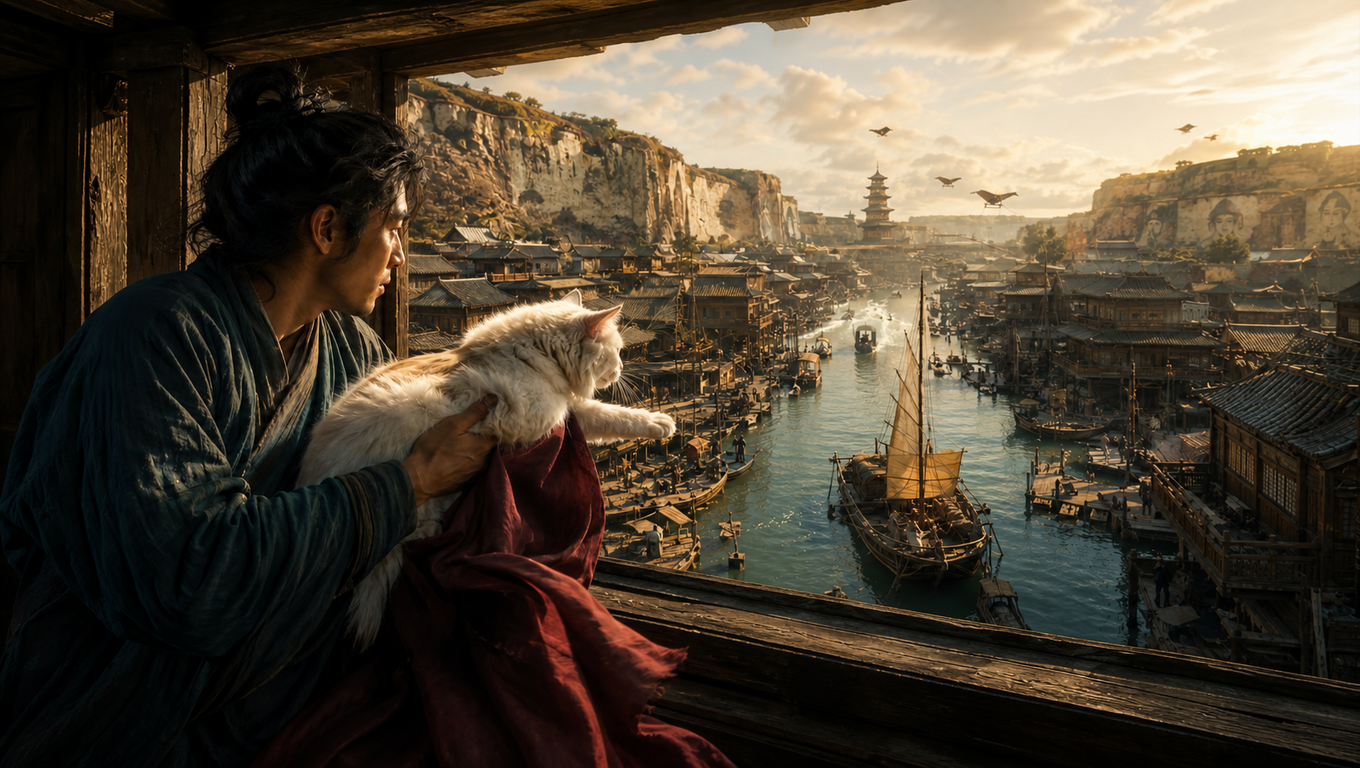 |
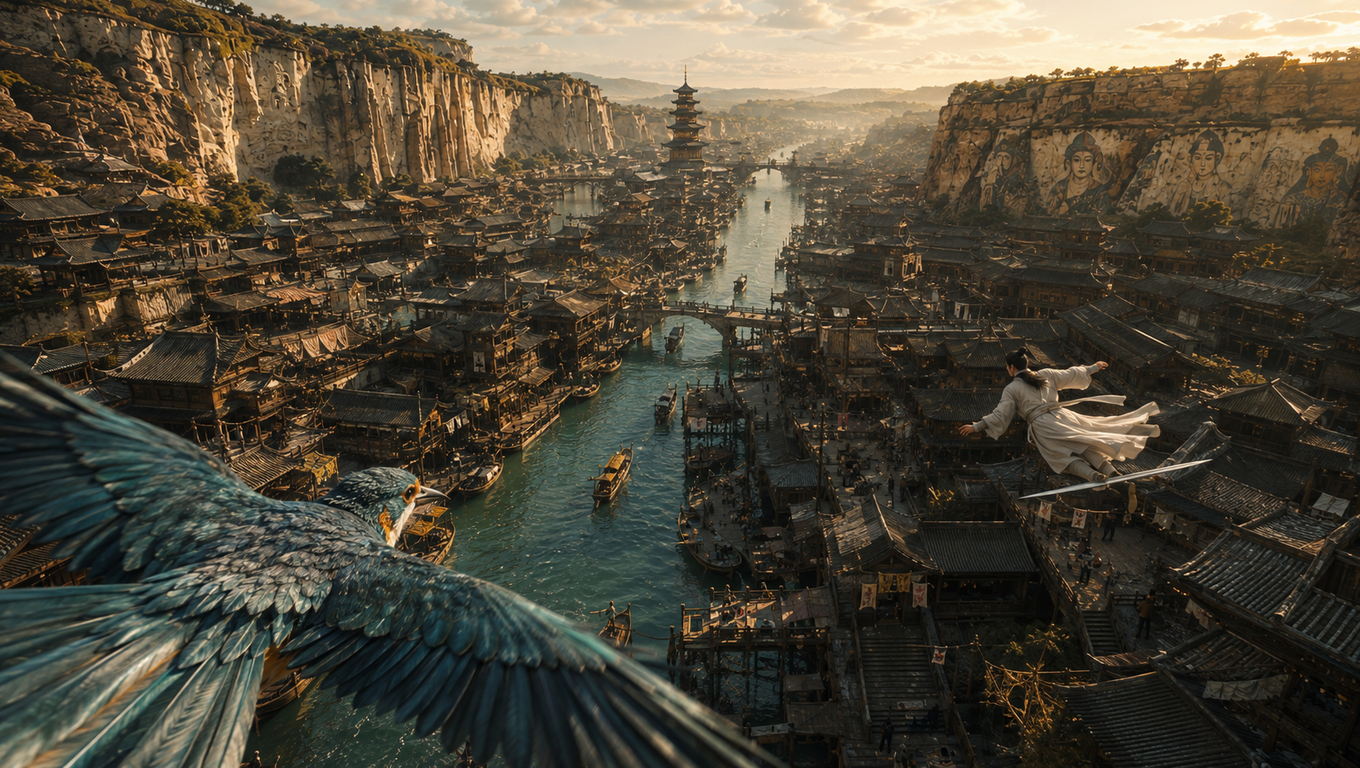 |
prompts/image/first.png |
prompts/image/last.png |
Render it with:
python src/inference/infer.py \
  --config configs/inference/8nfe_tuned_fp8.yaml \
  checkpoint=ckpts/stage-dmd-step-250 \
  render.prompt_file=prompts/image/example_fl2va.pt \
  render.out=results/example_fl2va.mp4
For your own keyframes, encode the prompt together with the images first:
python src/inference/encode_keyframes.py --prompt "..." \
  --first first.png --last last.png --out prompts/image/mine.pt
--first alone is I2VA, --last alone is L2VA, and both is FL2VA. Each mode wants its own instruction as the prompt's first line, given by MiniMax-H3's prompt writing guide.
Choosing an inference configuration
We support both single-GPU and multi-GPU inference for the released model. Single-GPU scripts auto-detect the best kernels for your GPU. Multi-GPU scripts vary by hardware:
bash scripts/inference/8nfe_tuned_fp8.sh                # one GPU
bash scripts/inference/8nfe_tuned_fp8_ulysses_h200.sh   # eight H200s, one node
bash scripts/inference/8nfe_tuned_fp8_ulysses_b200.sh   # eight B200s, one node
Results
Our fastest reported result uses SGLang Diffusion on 8×B200 GPUs: 6.9 seconds for denoising and about 9.0 seconds end-to-end for a 768p, 14.4-second video. The tables below compare its steady-state denoising speed with our reference inference pipeline on H200s and B200s:
H200:
| Configuration | GPUs | Seconds/NFE | 50 NFE (VDN-H3-50-step) | 8 NFE (VDN-H3-8-step) |
|---|---|---|---|---|
| dense MiniMax-H3 | 1 | 32.7 | 27.3 min | 4.4 min |
| VDN-H3 FP8 | 1 | 11.2 | 9.4 min | 90.5 s |
| VDN-H3 FP8 Distributed | 8 | 2.29 | 1.9 min | 18.3 s |
B200:
| Configuration | GPUs | Seconds/NFE | 50 NFE (VDN-H3-50-step) | 8 NFE (VDN-H3-8-step) |
|---|---|---|---|---|
| dense MiniMax-H3 (cuDNN) | 1 | 16.74 | 13.95 min | 2.23 min |
| VDN-H3 FP8 | 1 | 6.41 | 5.3 min | 51 s |
| VDN-H3 FP8 Distributed | 8 | 1.40 | 1.2 min | 11.23 s |
| SGLang Diffusion, VDN-H3 FP8 Distributed | 8 | 0.88 | 44.0 s | 6.9 s |
We exclude model loading, warm-up, VAE decoding, and MP4 encoding. For a live setup, we recommend running the text prompt rewriter, VAE decoding, and MP4 conversion on separate machines, so the eight GPUs only perform denoising.
Acknowledgement
VDN-H3 is built on MiniMax H3 and starts from its released transformer weights. We also thank Diffusers, FlashAttention, and Triton, on which the optimized inference path is built. We thank Kernel Design Agents (KDA) for kernel design support. We also thank Flash Linear Attention (FLA) and FlexAttention for their open-source attention implementations.
BibTeX
@misc{xi2026videodeltanet,
  title  = {VideoDeltaNet on MiniMax H3},
  author = {Haocheng Xi and Yiming Xie and Hexu Zhao and Yiwen Zhang and Michael Liu and Thomas Creavin and Kurt Keutzer and Xiuyu Li and Zhaoyang Lv and Chenfeng Xu and Haiwen Feng},
  year   = {2026},
  url    = {https://openvdn.github.io/}
}
License
VDN-H3 is a derivative of MiniMax-H3 and is distributed under the MiniMax H3 Community License Agreement, included here verbatim from the upstream repository.
The agreement grants rights only in its applicable territory, defined as worldwide excluding the European Union, the United Kingdom, the Republic of Korea, and the United States of America. It states that use outside the applicable territory is not authorized and invites people in an excluded territory to contact MiniMax about obtaining a license.
The agreement also contains redistribution requirements and an Acceptable Use Policy. Among other requirements, a distribution must include the agreement, modified files must carry notices of their modification, and distributions to third parties other than through hosted services must include the NOTICE file supplied with the code repository. Please read the agreement in full before using or distributing VDN-H3. This note is not a substitute for the license text or for legal advice.
- Downloads last month
- 664